Kubernetes autoscaling / Interactive field guide
From a busy microservice to ready Kubernetes capacity.
A traffic spike does not create a node directly. Follow one microservice through the control loops, then inspect the requests, policies and readiness conditions between a recommendation and usable capacity.
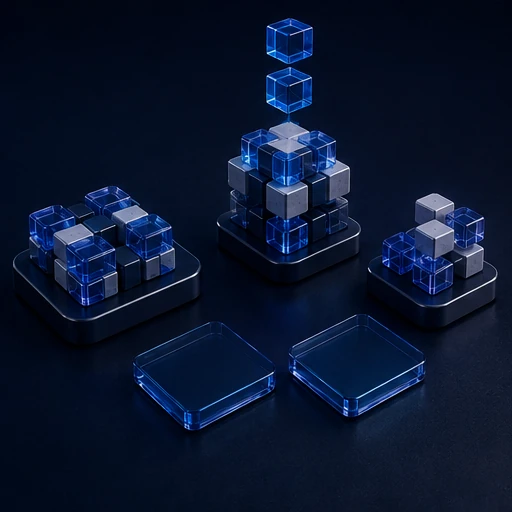
- 01 / Observe
Observe the selected microservice. Other services have independent scaling decisions.
- 02 / Recommend
HPA computes a replica recommendation, then applies tolerance, bounds and behavior.
- 03 / Create Pods
The scale target changes. Deployment and ReplicaSet controllers manage the Pods.
- 04 / Schedule
The scheduler needs compatible capacity. Excess target Pods remain pending.
- 05 / Provision
A node autoscaler may provision nodes; provider capacity and initialization still matter.
- 06 / Ready gate
Only Ready Pods add serving capacity. Consolidation needs a separate safe drain decision.
Initial example: three API Pods use 600m CPU each against a 500m request and a 60% target. The raw recommendation is six Pods. Two existing nodes have 2,000m usable CPU each; one additional node is required. The animation compresses conceptual stages, not real provisioning time.
Observe one microservice
- Deployment controlled by this HPA
- API service
- Current Ready Pods
- 3
- CPU usage / request
- 120%
- Raw recommendation
- 6
Apply HPA behavior
- Target CPU utilization (%)
- 60
- Maximum replicas
- 12
- Highest prior recommendation in 5 minutes
- 3
- Desired Pods
- 6
- Policy decision
- Scale-up requested
Find schedulable capacity
- Additional nodes permitted
- 2
- Additional nodes
- 1
- Unschedulable target Pods
- 0
- Consolidation candidates
- 0
02 / Follow the flow
Four boundaries. One connected explanation.
Each card explains a node in the diagram. Highlights show which boundaries contribute to the current result.
CPU signal
Measure the right denominator
HPA reads a metric for its scale target. For CPU utilization, usage is compared with requested CPU across the relevant containers; CPU limits are not the denominator. This engagement used identical requests and complete samples from Ready Pods. Actual HPA conservatively handles missing samples and initializing Pods, discards failed or terminating Pods for resource metrics, and can use custom or external metrics instead. Queue deadlines often need a backlog signal rather than CPU.
HPA target
Normalize a recommendation before writing scale
For this complete metric population, raw replicas equal ceil(current replicas × current utilization / target utilization). The 10% tolerance avoids small changes. Minimum and maximum bounds, recent recommendation history and scaling policies are separate controls. Default upscale behavior allows the larger of four Pods or 100% over 15 seconds; this engagement had no earlier events in that period. Default downscale stabilization uses the highest recommendation in a 300-second window. HPA writes the scale subresource; Deployment and ReplicaSet controllers manage Pods.
Node fleet
Unschedulable Pods can trigger provisioning
The scheduler considers requests and placement constraints, not a promise from the HPA. A node autoscaler may provision capacity that fits pending Pods, subject to node policy, quota and provider availability. Cluster Autoscaler typically expands configured node groups; Karpenter can choose node configurations from NodePool constraints. The CPU-only diagram shows a packed target layout, not actual scheduler assignments. New nodes may still need initialization before Pods can start.
Ready path
Capacity is useful only after readiness
Desired, scheduled, Running and Ready are different states. Startup and readiness probes keep warming applications out of serving endpoints. After load falls, fewer replicas do not instantly reduce the bill: nodes must be eligible for consolidation, with feasible drains, placement and storage. PDBs can constrain voluntary node drains, but do not directly veto an HPA or Deployment replica reduction. Maintain service floors and verify latency, queue age and recovery before claiming an optimization.
03 / Keep the model honest
One observation, with its boundaries visible.
utilization = observed_CPU / requested_CPU × 100
raw_replicas = ceil(current_replicas × utilization / target)
within_10_percent_tolerance → keep current recommendation
apply min=1, maxReplicas, recent downscale history
upscale cap = current + max(4,current), assuming no prior 15s events
required_nodes = ceil(total requested CPU / usable node CPU)
additional_nodes = min(permitted_extra, max(0,required−existing))
pending = desired Pods that still cannot fit
consolidation_candidates ≠ authorized node deletions- The HPA control loop normally runs periodically (15 seconds by default), not continuously. The brief visualization is a compressed explanation, not a clock or a cloud provisioning SLA.
- Every selected Pod is initially Ready and has the same CPU request and observed usage. Actual missing or unready metrics dampen scaling; multiple metrics choose the largest recommendation and failed metrics can block downscaling.
- The history assumption summarizes the highest recent recommendation. It does not simulate a rolling history buffer or earlier scale changes in the last 15 seconds.
- Node capacity is usable after system reservations. Requests are powers-of-two multiples of 250m and divide the supported node sizes; the shown packing ignores all non-CPU constraints.
- A missing CPU request reserves no CPU in this arithmetic but does not mean a Pod consumes no resources. It makes the HPA utilization metric unavailable.
- Consolidation candidates remain billed in the displayed capacity cost until a separate drain/removal decision succeeds. The $2 per node-hour figure is the planning rate used in this engagement, not a provider price.
- The small cluster does not generate the separate $2M portfolio bill. More traffic can increase instantaneous capacity cost even when good autoscaling reduces idle spend over a normalized month.
04 / Think it through
Questions behind the example.
Why do three API Pods at 120% utilization and a 60% target produce six desired Pods, and why is one additional node required?
Why would a zero extra-node allowance leave three target Pods unschedulable without changing the HPA recommendation?
How does a larger CPU request change the utilization denominator without proving that the application is faster or cheaper?
How does downscale stabilization differ from node consolidation and its disruption constraints?
Why does one service’s HPA not solve a bottleneck in another microservice or dependency?
Primary documentation